Quick answer
A workflow automation pilot plan should cover one end-to-end journey, a defined user group, real integrations, named exception owners, and a fixed measurement window. Before development begins, set thresholds for completion, integration reliability, adoption, manual time saved, conversion impact, and unresolved risk. Scale only when the workflow creates measurable value without transferring hidden work to employees or customers.
What should a workflow automation pilot plan prove?
The pilot should prove that one valuable workflow can run from trigger to business outcome reliably, with manageable exceptions and enough user adoption to justify further investment.
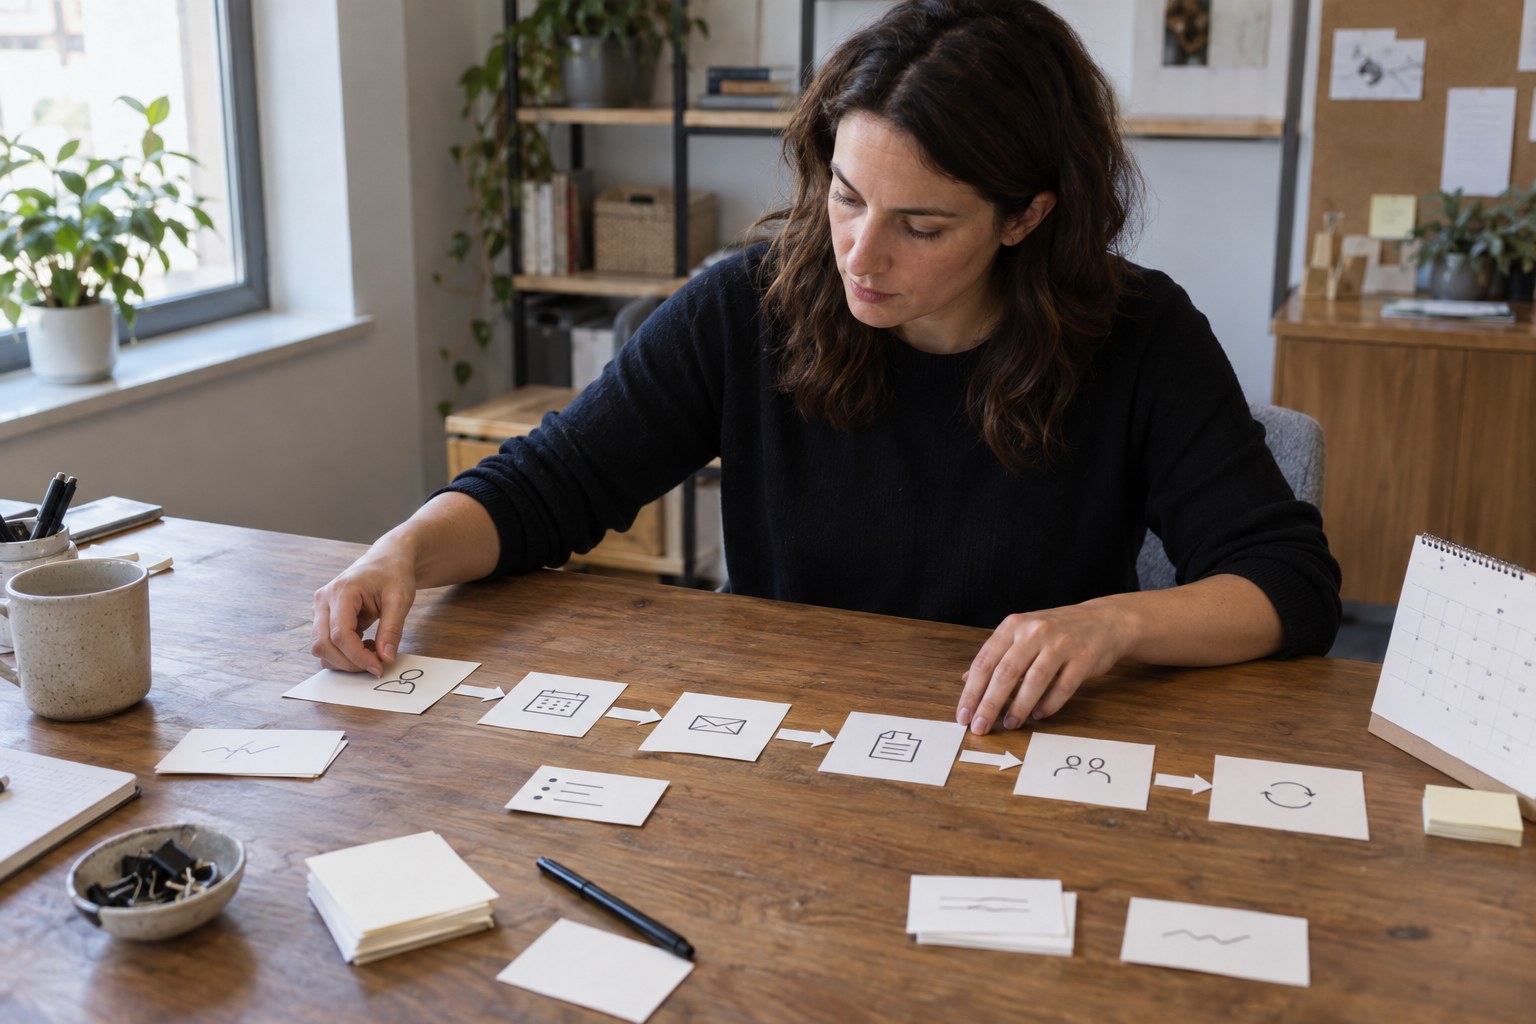
Choose a journey, not a feature. “Automate appointment intake” is testable: a customer submits details, the system checks availability, creates the booking, sends confirmation, and gives staff a route for conflicts. “Add AI” is merely an expensive mood. Define the starting event, successful end state, participating systems, authorized users, excluded cases, and human owner before selecting technology. If the journey cannot be drawn on one page, it is probably several pilots pretending to be one.
- One trigger and one measurable business outcome
- One representative user group and a named process owner
- Production-like data and the minimum necessary integrations
- Explicit exclusions, exception routes, and rollback conditions
- A baseline measured with the current manual process
The boundary must include the awkward middle. Authentication failures, duplicate submissions, unavailable staff, invalid records, and customer abandonment are part of the workflow, not debris to sweep into phase two. Design the automation to human handoff before launch so a failed step creates a visible task with context, ownership, and status. The practical implication is simple: approve the pilot brief only when success and safe failure are both observable.
A useful boundary test is to ask what happens at 4:55 p.m. when the final integration rejects a valid request. If the answer is “someone will notice,” the pilot lacks an operating design. Specify which queue receives the case, what information accompanies it, who may retry or override it, and how the customer is informed. This does not require automating every rare event. It requires preventing rare events from becoming invisible liabilities while the headline success rate looks respectable.
Build the pilot scorecard before development
Use a scorecard with baseline, target, evidence source, owner, and decision rule for every outcome. Targets agreed after results arrive are decorations, not controls.
Measure the whole operating result rather than whether individual steps executed. A technically successful workflow can still create duplicate records, encourage staff workarounds, or move effort from employees to customers. Record the current baseline first, then set thresholds that reflect the economics and risk of this specific process. The workflow automation compliance checklist should run beside the scorecard when personal data, permissions, retention, or regulated decisions are involved.
| Measure | Evidence | Decision rule |
|---|---|---|
| End-to-end completion | Event log plus outcome record | Scale only if the agreed target is met |
| Exception handling | Exception register with owner and resolution | Revise if cases are hidden or ownerless |
| Integration reliability | Requests reconciled across connected systems | Stop if mismatches can corrupt operations |
| User adoption | Eligible cases compared with actual use | Investigate low use before adding features |
| Operational time saved | Baseline minutes minus pilot minutes | Scale when net savings survive support effort |
| Conversion impact | Comparable eligible outcomes | Treat as directional unless volume is adequate |
Assign one person to reconcile the evidence, because analytics assembled by separate vendors rarely agree by magic. Define red lines independently of the combined score: unauthorized access, unrecoverable data loss, or an exception without an accountable owner can stop a pilot even when every efficiency measure is green. The next action is to have operations, product, engineering, and compliance sign the same scorecard before build approval.
Do not collapse the scorecard into one weighted number. A pleasant adoption result cannot compensate for corrupted customer records, and strong time savings cannot excuse an unsafe permission model. Use a gate structure instead: first pass security and data integrity, then reliability and recoverability, then adoption and commercial value. This ordering prevents a seductive average from hiding a fatal weakness. It also gives the team a useful diagnosis: failure at a gate identifies what must change before another pilot cycle.
How does the scorecard work in a real pilot?
Apply the scorecard to a limited cohort, calculate results from eligible cases, and include exception labor in the economics. The denominator should never improve because difficult cases quietly disappeared.
Assume a consultation business pilots an embedded booking workflow for 100 eligible requests. Its manual baseline is 12 staff minutes per request. During the pilot, 80 requests complete through automation, 12 are resolved through a human handoff, and 8 remain unresolved. Automated completions require 3 staff minutes each for review; handled exceptions require 10 minutes each. These are illustrative assumptions, not performance promises.
- Baseline labor: 100 × 12 minutes = 1,200 minutes.
- Pilot labor: 80 × 3 minutes + 12 × 10 minutes = 360 minutes.
- Gross labor reduction: 1,200 − 360 = 840 minutes.
- Resolved-journey rate: (80 + 12) ÷ 100 = 92%.
- Unresolved rate: 8 ÷ 100 = 8%; these cases remain a decision blocker if the agreed ceiling is lower.
The result does not automatically justify scaling. Reconcile every booking with the source system, inspect why the eight cases failed, verify whether staff actually used the intended route, and compare conversion with an appropriate baseline. If the 840-minute reduction excludes monitoring, customer recovery, or duplicate cleanup, recalculate it. For integration-heavy workflows, the api sdk workflow integration architecture should expose identifiers, retries, and status changes needed for that reconciliation. The decision is based on net operational improvement after exceptions, not the automation’s happiest path.
When should you revise or stop the pilot?
Revise when the value is credible but a bounded design flaw prevents reliable operation. Stop when the workflow lacks sufficient value, safe recovery, trustworthy data, or willing users.
A pilot is not suitable when the process changes every week, the baseline is unknown, the event volume cannot reveal recurring failures, or a mistake could cause unacceptable harm without immediate recovery. It is also a poor tool for disguising an unresolved policy decision. Software cannot decide who may approve a refund, access a record, or override a clinical restriction until the business does. In those cases, stabilize the rules or run a manual service rehearsal first.
- Scale: mandatory gates pass and measured value survives full operating costs.
- Revise: failure has a specific cause, owner, remedy, and retest condition.
- Extend measurement: evidence is inconclusive, but continued exposure is safe.
- Stop: data integrity, authorization, recovery, adoption, or economics fail without a credible bounded fix.
Watch for shadow labor: employees checking every automated result, maintaining private spreadsheets, or contacting customers after silent failures. Interview users and observe several cases rather than trusting logs alone. For customer-facing consultations, test the entire route from identity and scheduling through the embedded video consultation on website, session completion, and follow-up. A polished call screen cannot rescue broken intake. The useful implication is to fund scale only after operational evidence and frontline behavior tell the same story.
Workflow automation pilot plan: an ordered implementation path
Run the pilot as a controlled operating change: baseline the journey, define gates, build the smallest complete version, instrument it, release it to a bounded cohort, and hold a documented decision review.
- Map the current journey, baseline labor and outcomes, and name the process owner.
- Select one cohort; document inclusions, exclusions, permissions, and rollback triggers.
- Approve the scorecard, evidence sources, red lines, and scale-or-stop thresholds.
- Build the minimum end-to-end workflow with logs, reconciliation, and human recovery.
- Test normal, duplicate, delayed, denied, unavailable, and abandoned cases.
- Release gradually; review exceptions and frontline behavior throughout the measurement window.
- Reconcile results against the baseline and record a scale, revise, extend, or stop decision.
Give every decision an owner and every failed case a durable identifier. Development is complete only when operators can see what happened, recover safely, and distinguish a retry from a duplicate. Modern vibe coding can accelerate interface prototypes and internal tools, but generated code does not relax requirements for access control, integration contracts, tests, or maintainability. Use it inside the same engineering review as any custom software.
End with a decision record containing results, unresolved risks, required changes, operating cost, and the next funding boundary. If live conversation is the journey’s decisive step, test it inside the workflow rather than sending users to a detached meeting tool. Scrile Stream is relevant when a business needs branded video calls embedded in its website, with an integration path ranging from a simple embed to a customized API or SDK build. The immediate next action is still the scorecard: approve the evidence before commissioning the full implementation.
Hold the final review with the people who operate, support, govern, and fund the workflow. Engineering can explain failure modes; frontline staff can reveal hidden effort; compliance can identify unacceptable exposure; the sponsor can judge whether the verified outcome merits more capital. Preserve the pilot logs, decision record, test cases, and exception taxonomy as implementation assets. If the result is “revise,” authorize only the named remedy and retest scope. Otherwise, a bounded experiment quietly turns into an unbounded project.
Turn a proven consultation workflow into an owned experience
Once the pilot proves that scheduling, identity, exceptions, and follow-up work as one journey, the live session should not become an off-site detour. Keeping video inside the business website can preserve a branded path for support, coaching, telehealth, sales, or education.
Scrile Stream provides custom video call integration for websites through simple embeds or more tailored API and SDK implementations. It fits private, scheduled, recurring, or paid session workflows that need more control than a consumer meeting app, subject to the requirements established by your pilot.
Frequently asked questions
How long should a workflow automation pilot run?
Run it until the predefined cohort or case volume has passed through the complete journey and recurring exceptions can be assessed. Calendar duration alone is a weak stopping rule.
What should be included in a workflow automation pilot plan?
Include the journey boundary, cohort, baseline, integrations, owners, exception handling, evidence sources, decision thresholds, red lines, rollback method, and final review date.
How do you choose the first workflow to automate?
Choose a stable, repeated, measurable workflow with meaningful operating cost, accessible data, manageable failure consequences, and an accountable business owner.
What is the difference between a pilot and an MVP?
An MVP tests whether a product proposition creates value for users. A workflow pilot tests whether a defined operational journey performs reliably and economically under real conditions.
Which metrics matter most in an automation pilot?
Track end-to-end completion, exception resolution, integration reliability, adoption, net operational time saved, business outcome, and any mandatory security or compliance gates.
When should a workflow automation pilot be stopped?
Stop when unsafe access, unreliable data, unrecoverable failures, persistent non-adoption, or poor economics lack a credible and bounded remedy.
Can AI-generated code be used in a workflow pilot?
Yes, but it should receive the same architecture, security, testing, review, and maintenance controls as manually written custom software.
Who should approve scaling after the pilot?
The business owner should decide with evidence reviewed by operations, engineering, frontline users, and compliance or security stakeholders relevant to the workflow.
Project lead at Scrile. Helps clients pick what actually moves growth and bridges them with the engineering team. Writes about the operational side of software delivery — scoping, requirement translation, and vendor-team alignment.